GitHub Copilot Fusion Expands to New Surfaces, Adds Models and Benchmark Results
· GlobeWire Daily Editorial Desk · Source: github.blog
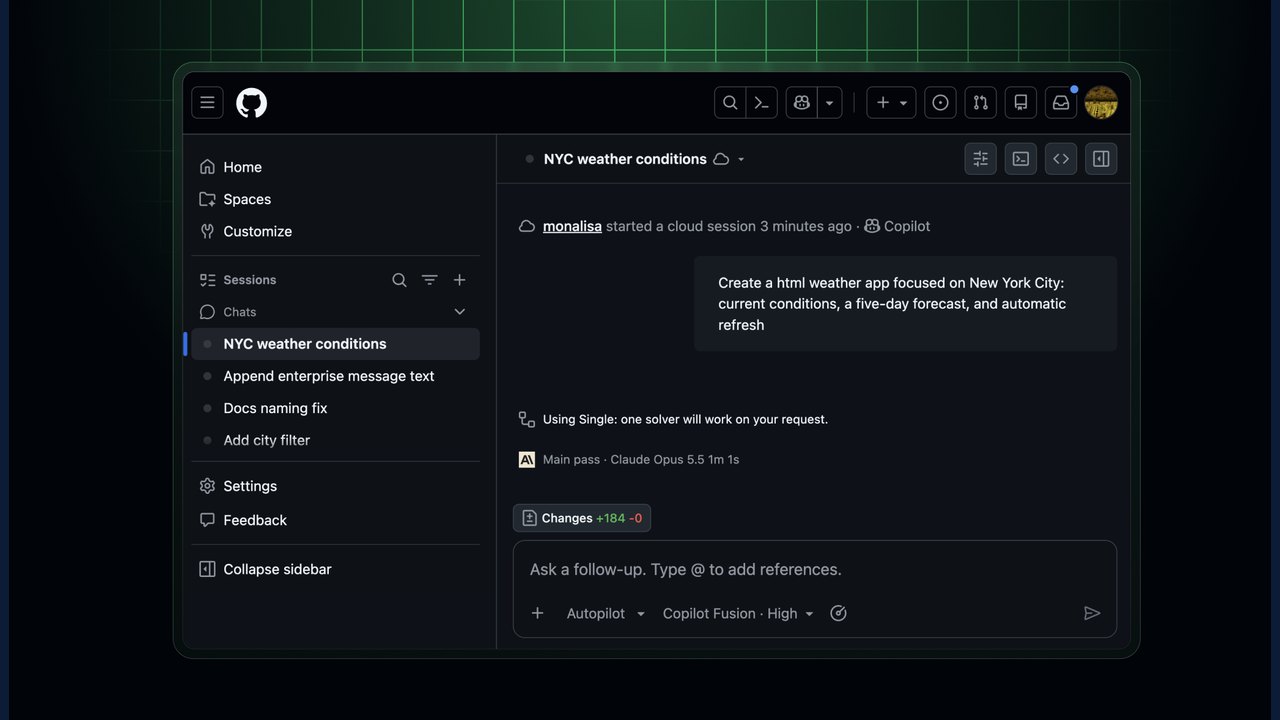
Image: The GitHub Blog · Photo source · Resized and letterboxed to 16:9; no AI generation
GitHub has announced an update for GitHub Copilot Fusion, introducing expanded availability across multiple platforms, newly supported models, and performance results on public Terminal-Bench leaderboards.
According to the announcement, Copilot Fusion is now featured on the public Terminal-Bench 4.1 leaderboards hosted by Stanford, Harbor, and the Laude Institute. Terminal-Bench evaluates how AI agents handle difficult and realistic terminal tasks. On these leaderboards, Copilot Fusion Max reported a 71.2% resolution rate. The published figures indicate it scored 5.4 percentage points higher than certain leading frontier models, specifically Opus 5.5 and Fable 5.2, while citing lower relative costs in the comparison.
Expanded Platform Availability
Users can now access Copilot Fusion across additional surfaces where Copilot is integrated:
- Web: Available on the latest version of github.com.
- Integrated Development Environments: Available in Visual Studio.
- Mobile: Available in the GitHub Mobile beta applications for both iOS and Android, with production mobile app support scheduled for release shortly.
Model Integration and Configuration
When utilizing Copilot Fusion, users can select the feature within the model picker interface. The system is designed to choose and coordinate models automatically for individual tasks based on the user-configured effort level.
The update incorporates specific models into the Fusion tiers:
- Claude Sonnet 5.5 integrated into Copilot Fusion Max
- GPT-6.1 Terra integrated into Copilot Fusion High
- MAI-Code-2 integrated into Copilot Fusion Standard
Practical Implications and Verification
These updates provide developers with broader access to Copilot Fusion across web, desktop, and beta mobile environments, alongside benchmark metrics for comparative evaluation. Users interested in verifying these updates can review the official GitHub changelog and consult the independent Terminal-Bench leaderboards maintained by Stanford, Harbor, and the Laude Institute.
AI-assisted reporting; source claims are attributed and have not been independently verified.
More to read
 GitHub Announces Upcoming Deprecation of Selected Copilot Models for December 2026
 GitHub Copilot App Expands with Azure DevOps, Browser Use, and General Availability for Enterprise Server
 GitHub Deprecates Certain Copilot Models as of November 16, 2026
 GitHub Adds Industry Comparisons to the Copilot Impact Dashboard