Google, OpenAI, and Anthropic Commit to Unified AI Scraping Controls via New Robots.txt Directive
· GlobeWire Daily Editorial Desk · Source: www.engadget.com
Image: www.engadget.com — Creative Commons
Major artificial intelligence developers, including Google, Anthropic, OpenAI, and Microsoft, have announced plans to support a standardized robots.txt directive. According to published reports, the initiative is designed to give website operators a centralized method to manage how their content is harvested for generative AI training.
How the New Standard Works
Previously, website administrators were required to track and configure separate rules for individual AI crawlers from different providers. The newly adopted proposal—authored by Anthropic technical lead for standards Kevin Kelley and currently under consideration at the Internet Engineering Task Force (IETF)—introduces a single common signal.
Key practical details of the implementation include:
- Unified User-Agent: Publishers can utilize a designated user-agent identifier within their robots.txt file specifically targeting AI training data collection.
- Granular Control: Operators can block general AI training data harvesting while selectively permitting access to specific directories, such as press kits.
- Search Independence: The new directive is reported to affect only AI training crawlers and will not prevent websites from appearing in standard web search results.
For Google, the new signal will be interpreted specifically to restrict the "Google-Extended" user agent utilized for Gemini model training.
Timeline and Limitations
Implementation schedules vary among the participating companies:
- Anthropic: Reported to have already started supporting the new directive.
- OpenAI: Pledged to implement the signal in the coming months.
- Google and Microsoft: Both companies stated plans to support the directive in early 2027, with Microsoft specifying a target date of February 1, 2027.
Independent observers note important limitations to the announcement. Reported details emphasize that the directive cannot retract or alter data that has already been harvested during past crawling activities. The mechanism applies strictly to future data collection.
How to Verify
Website operators and administrators interested in monitoring or adopting these controls can review official announcements directly from the respective companies or track the open standards proposal through the IETF documentation repository.
AI-assisted reporting; source claims are attributed and have not been independently verified.
More to read
 When Human Writing Sets Off AI Detectors: What False Positives Mean for Writers
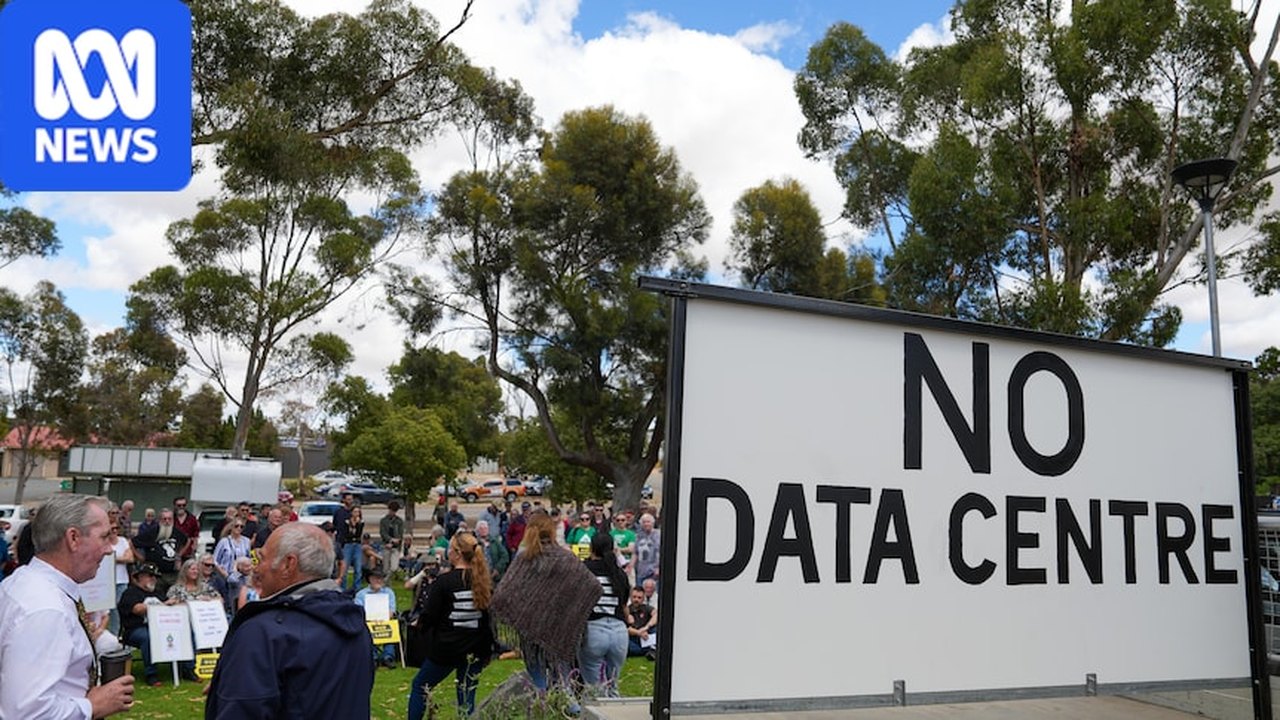 Adelaide Hills Communities Rally Against Proposed 1,200MW AI Data Centre
 AI Vendors Re‑Examine Data‑Sharing Rules as Customers Push Back on Shared Model Training
 ChatGPT Share Link Flaw Allowed Unauthorized Access to Private Conversations
Trending on GlobeWire Daily
Selected from recent coverage and related topics; not live search rankings.
 Jio Platforms Valued at $131.5bn Following India’s Largest-Ever IPO
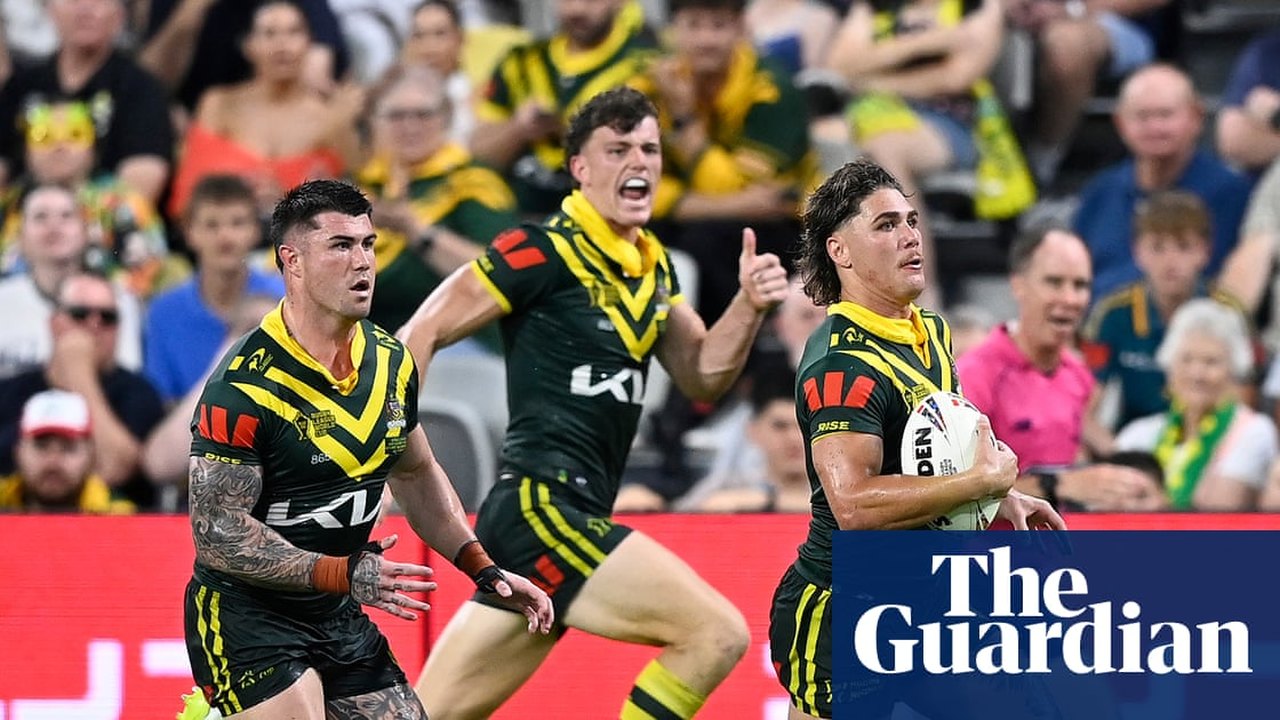 Walsh Sparks Australia to World Cup Win Over Cook Islands Amid Clinical Concerns
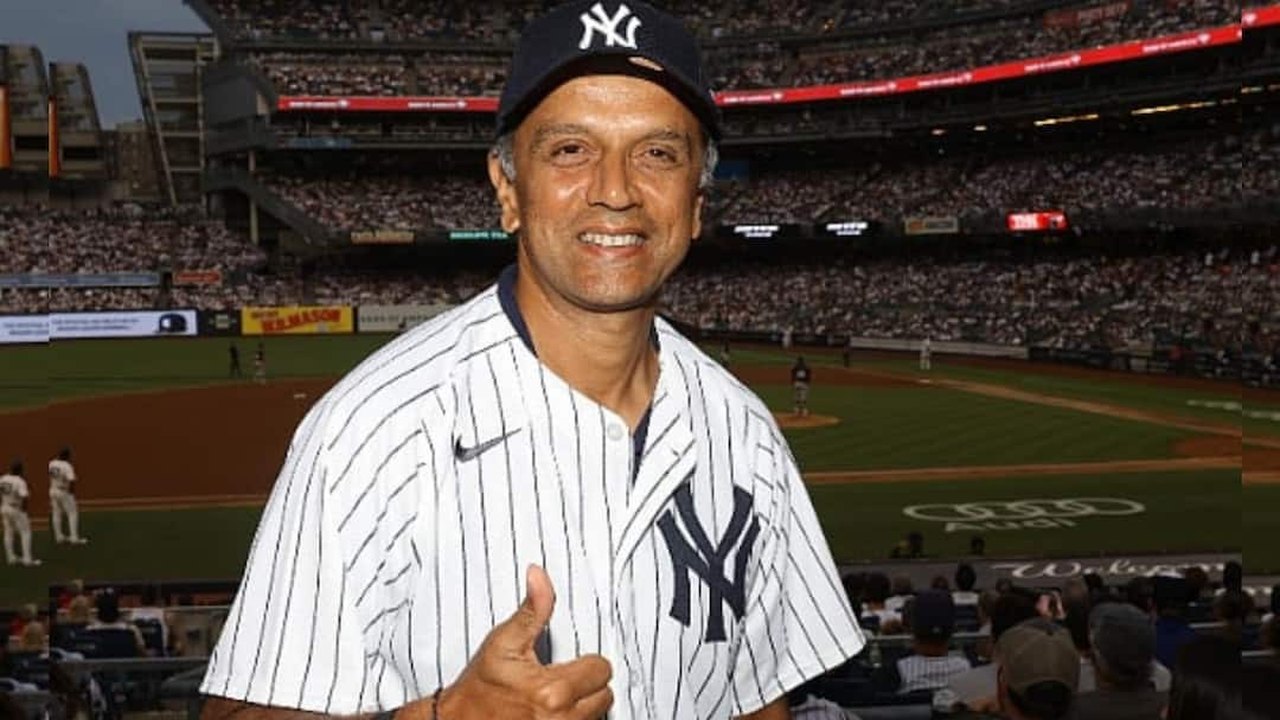 Former India captain Rahul Dravid nominated to senior board for 2030 Commonwealth Games preparations
 West Indies Secure 1-0 Lead Over Bangladesh in Mirpur Test
 Pujara and Nayar Debate Ravindra Jadeja's ODI Future Ahead of New Zealand Series
 Debate Intensifies Over Calls for United Nations Protection Force in Palestinian Territories